Industrial organizations have invested heavily in connectivity, dashboards, and AI—but still lack trust in the data. KPIs don’t always reconcile with plant-floor reality. Gaps, spikes, and inconsistencies appear without clear cause. Ownership is unclear, and dependencies are hard to trace.
Without visibility into how data is defined, structured, and used, analytics and AI initiatives stall before they scale.
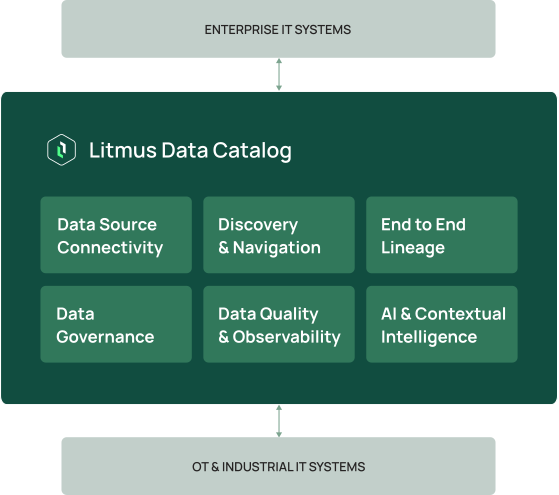
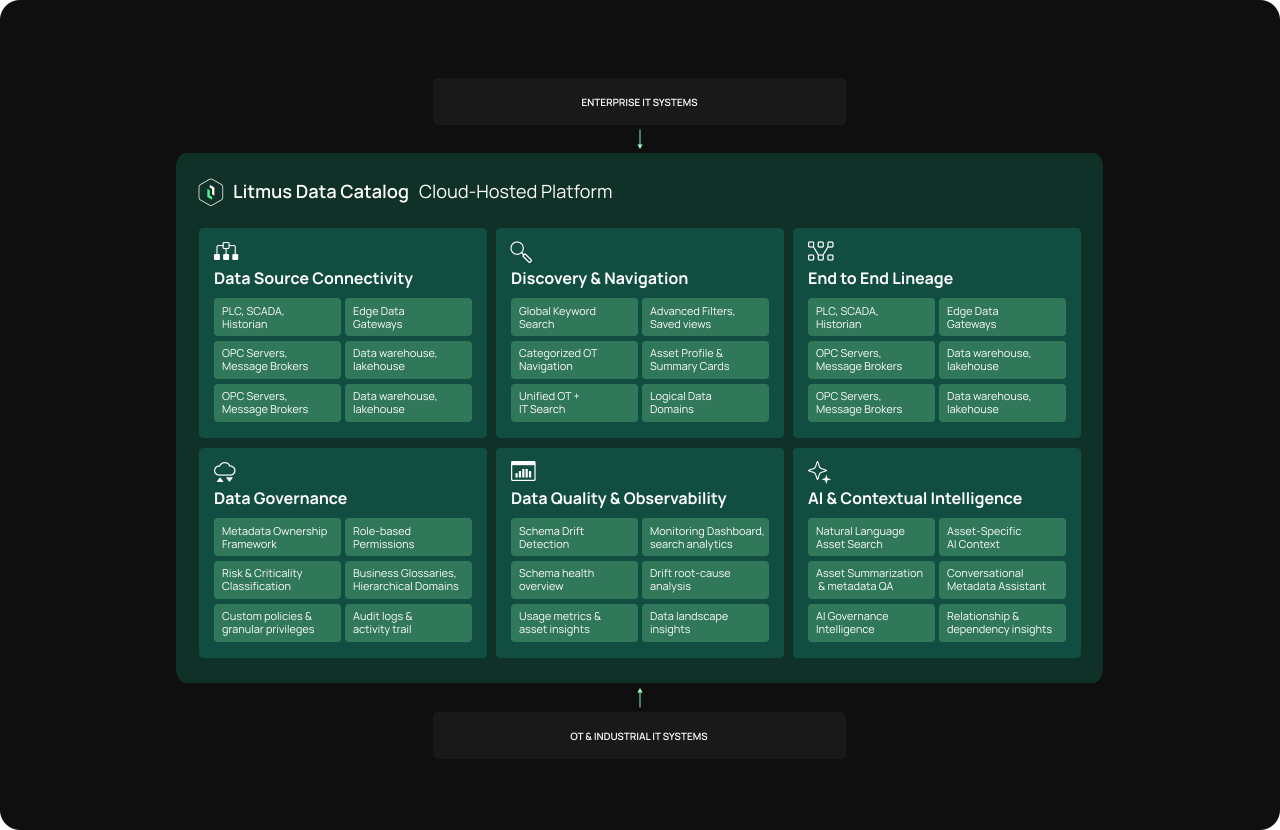
Litmus Data Catalog is the metadata and governance layer of the industrial data architecture.
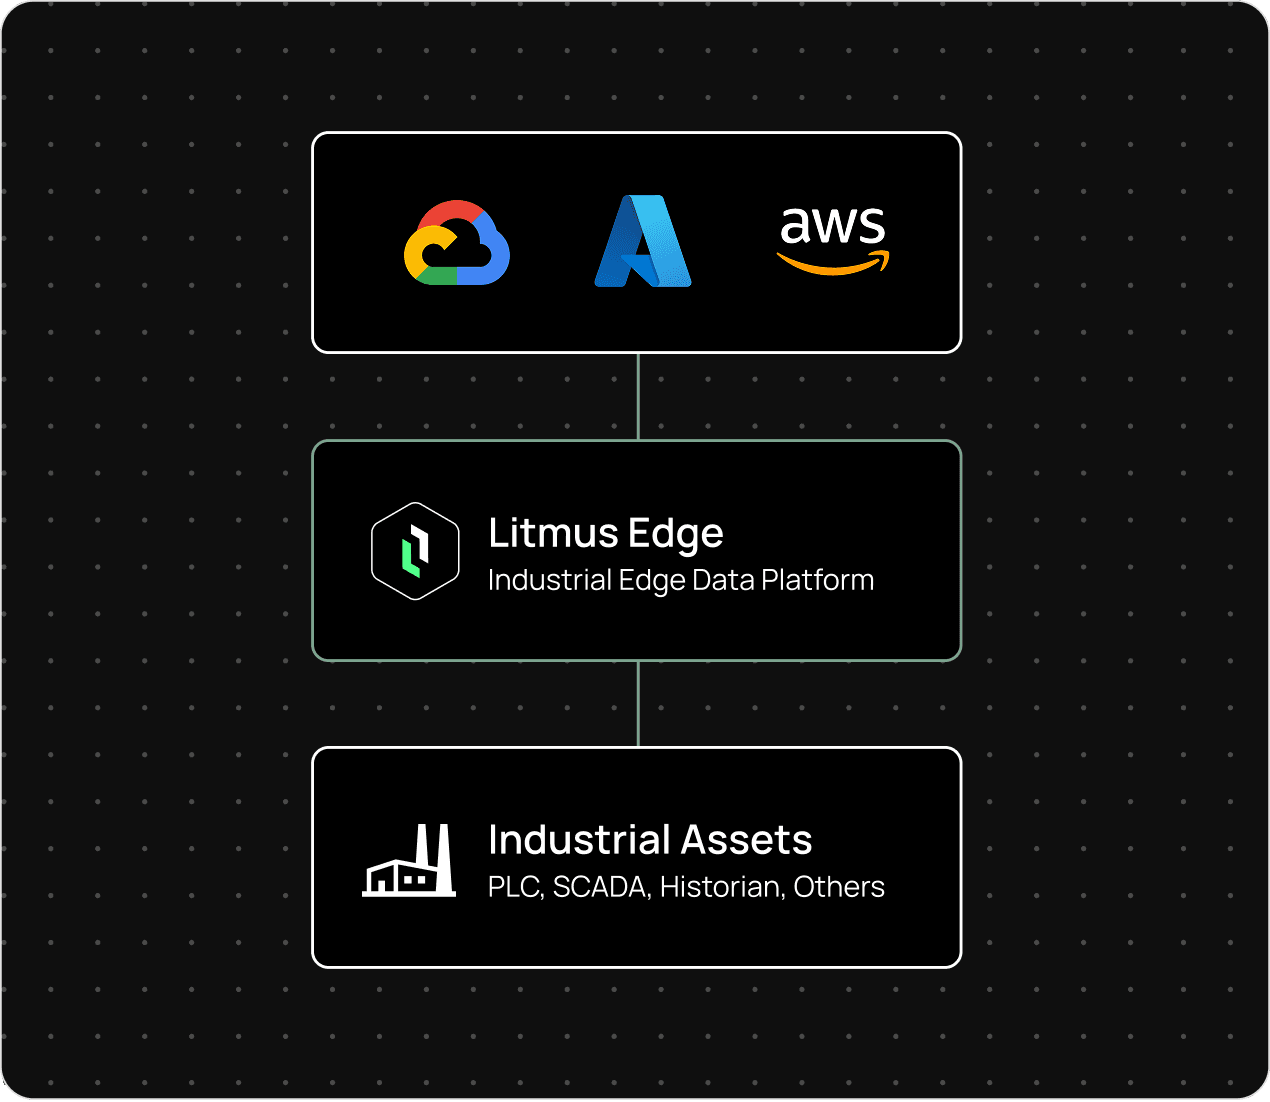
While Litmus Edge collects operational data and Litmus Unify governs real-time data exchange, Data Catalog makes data interpretable—exposing lineage, standardizing terminology, and assigning ownership so it can be trusted for analytics and AI.
standardized industrial data architecture
optimized packing and volume tracking
Real-time equipment monitoring across sites
Real-time monitoring and corrective action
Six capabilities that take industrial metadata from connected to discoverable, governed, monitored, and AI-ready.
DATA SOURCE CONNECTIVITY
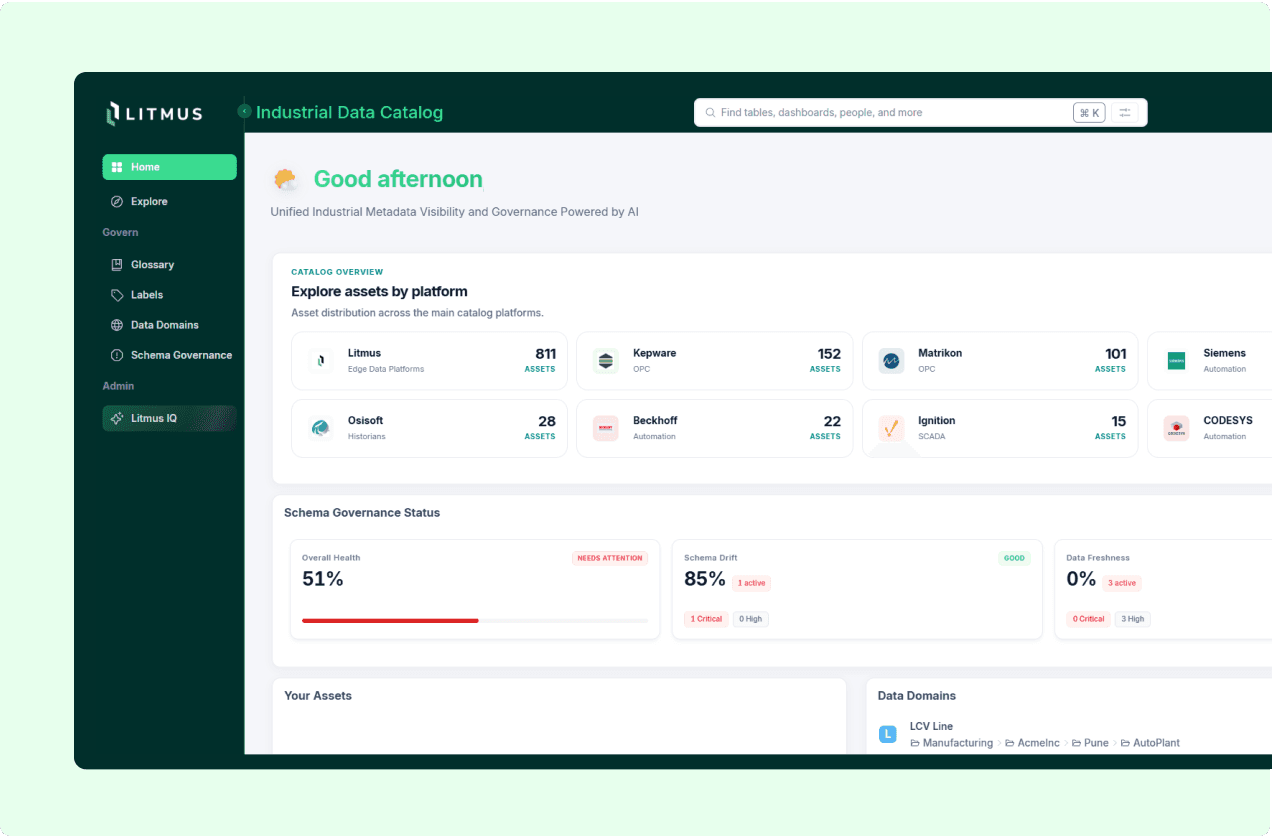
Industrial data doesn't live in one system—it's distributed across controllers, plant software, edge infrastructure, and enterprise platforms. Litmus Data Catalog connects metadata across all of them, creating one unified view of what data exists across the environment, including in networks that never touch the internet.
Key features:
DISCOVERY & NAVIGATION
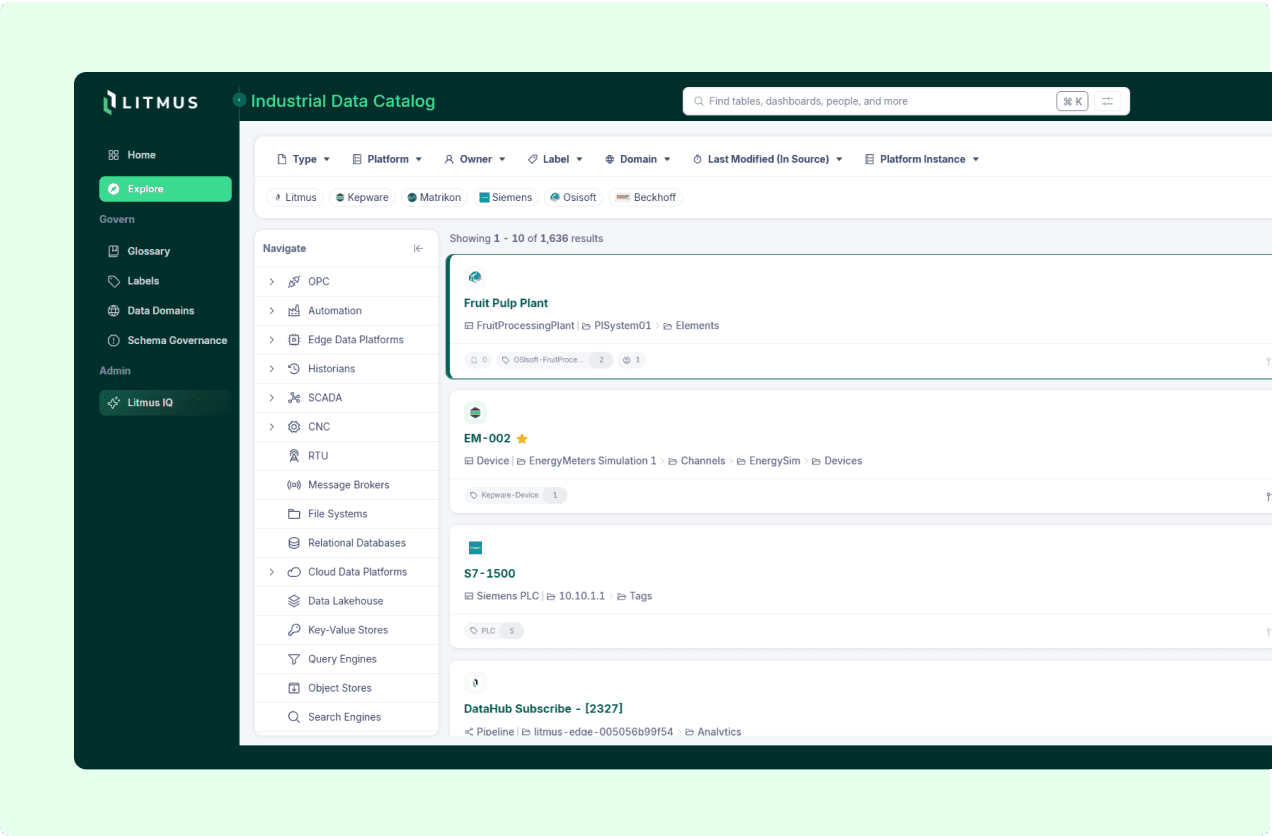
As metadata volume grows, finding the right dataset becomes a bottleneck. Litmus Data Catalog moves from flat search to structured exploration, so people can locate, understand, and maintain industrial data without depending on the one engineer who remembers where everything lives.
Key features:
END-TO-END LINEAGE
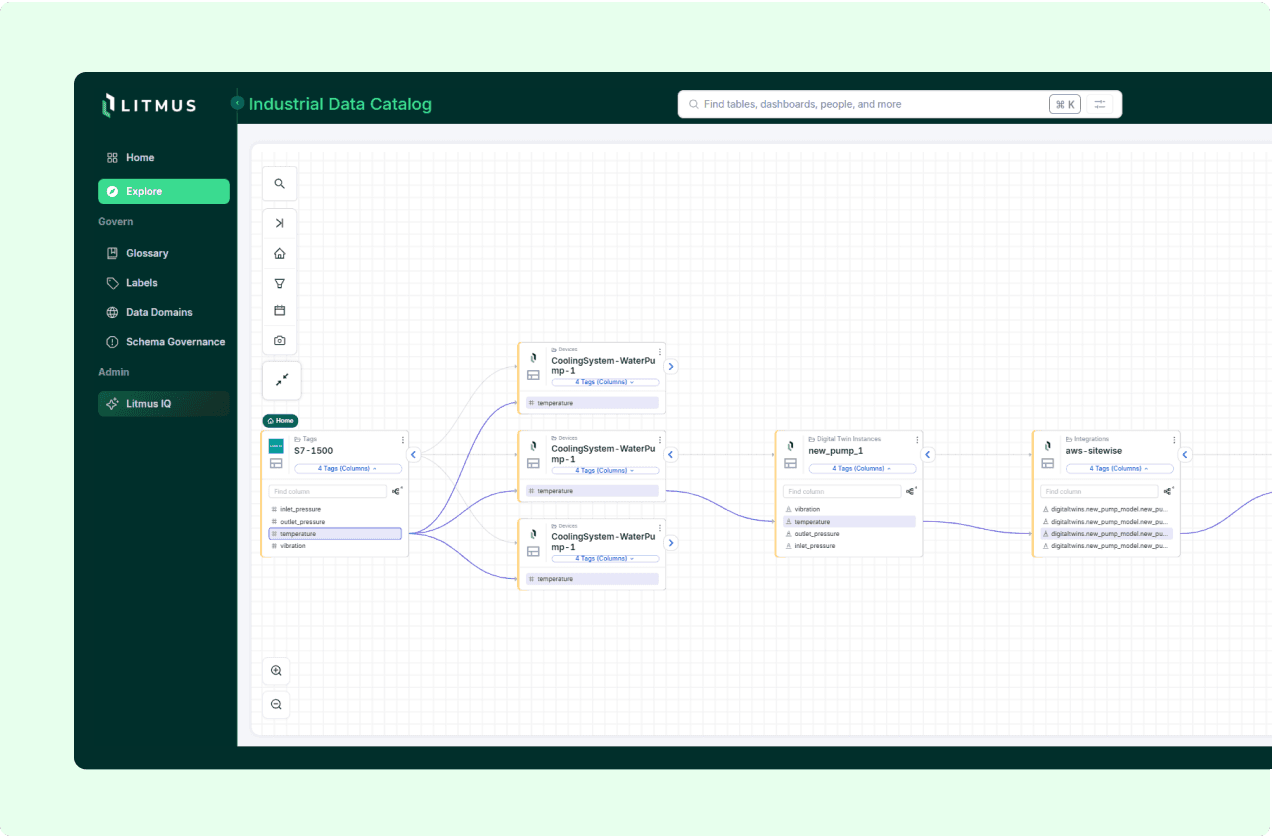
Industrial teams need to see how metadata connects across systems, and what breaks when something changes. Litmus Data Catalog provides end-to-end lineage down to the individual device and tag so teams can trace dependencies, troubleshoot faster, and assess downstream impact before a change is made, not after a dashboard goes wrong.
Key features:
Data Governance
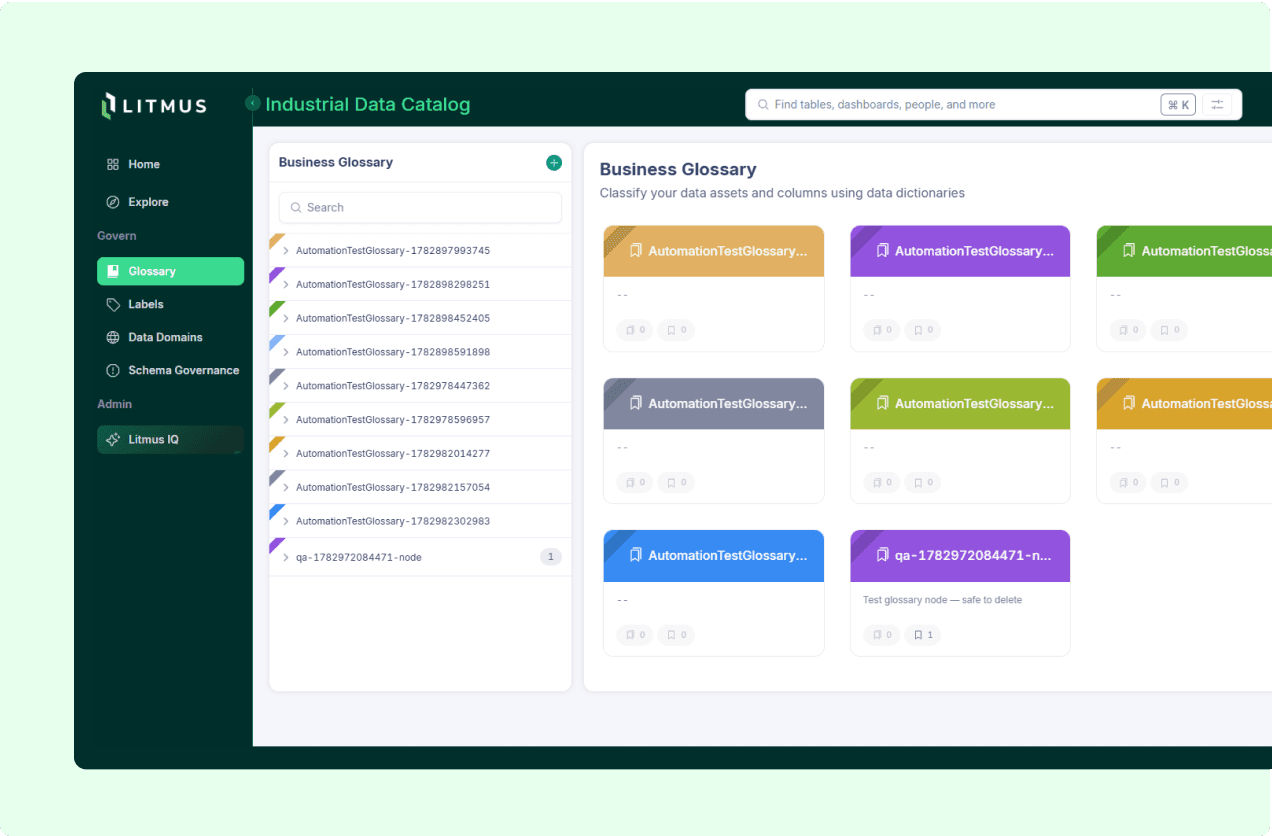
Metadata trust improves when governance is built in rather than documented after the fact. Litmus Data Catalog makes sure industrial data is consistently defined, owned, classified, and controlled across systems, sites, and teams—with domains that mirror how the business is actually organized, and a full audit trail of every change.
Key features:
DATA QUALITY & OBSERVABILITY
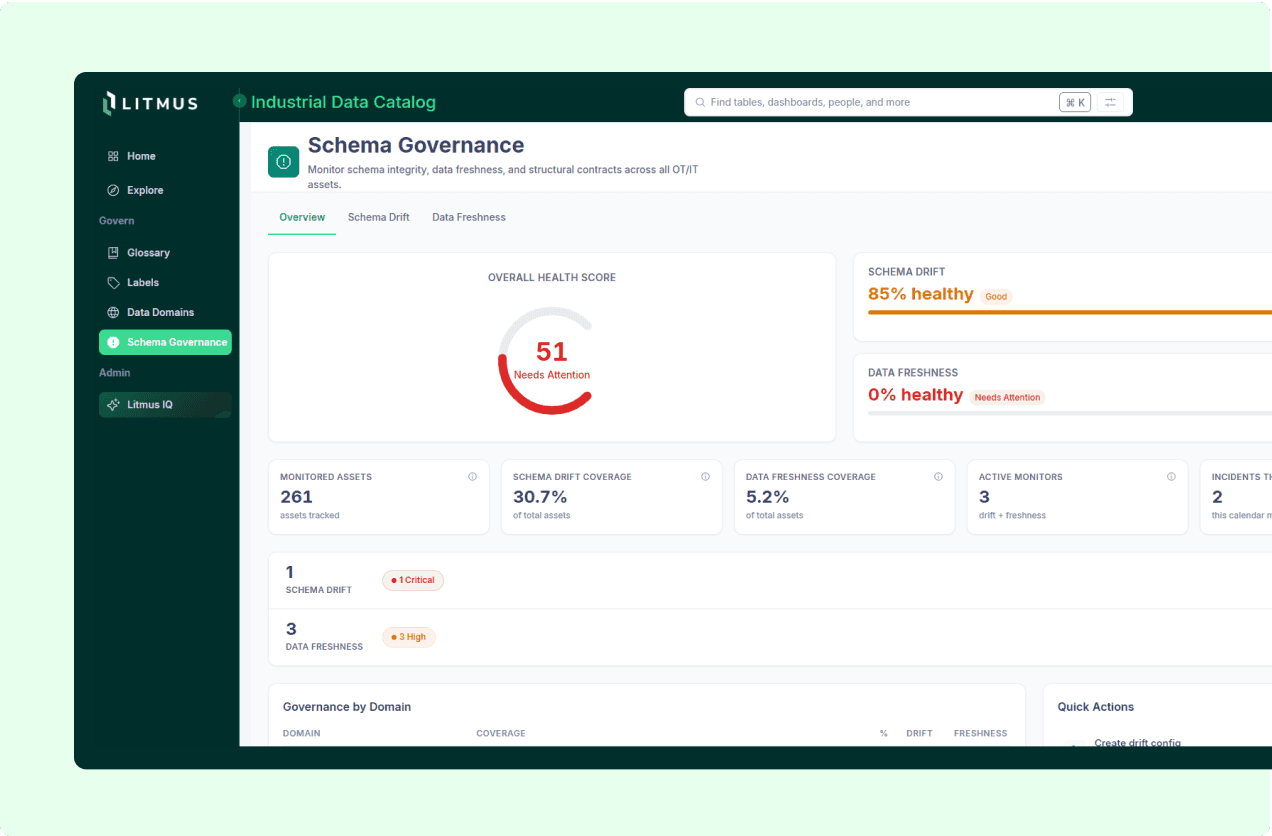
Metadata quality degrades quietly as source systems, schemas, and pipelines evolve. Litmus Data Catalog detects drift, explains what caused it, and reports on the health of the connected landscape, so issues are found before they reach a dashboard or a model.
Key features:
AI & CONTEXTUAL INTELLIGENCE
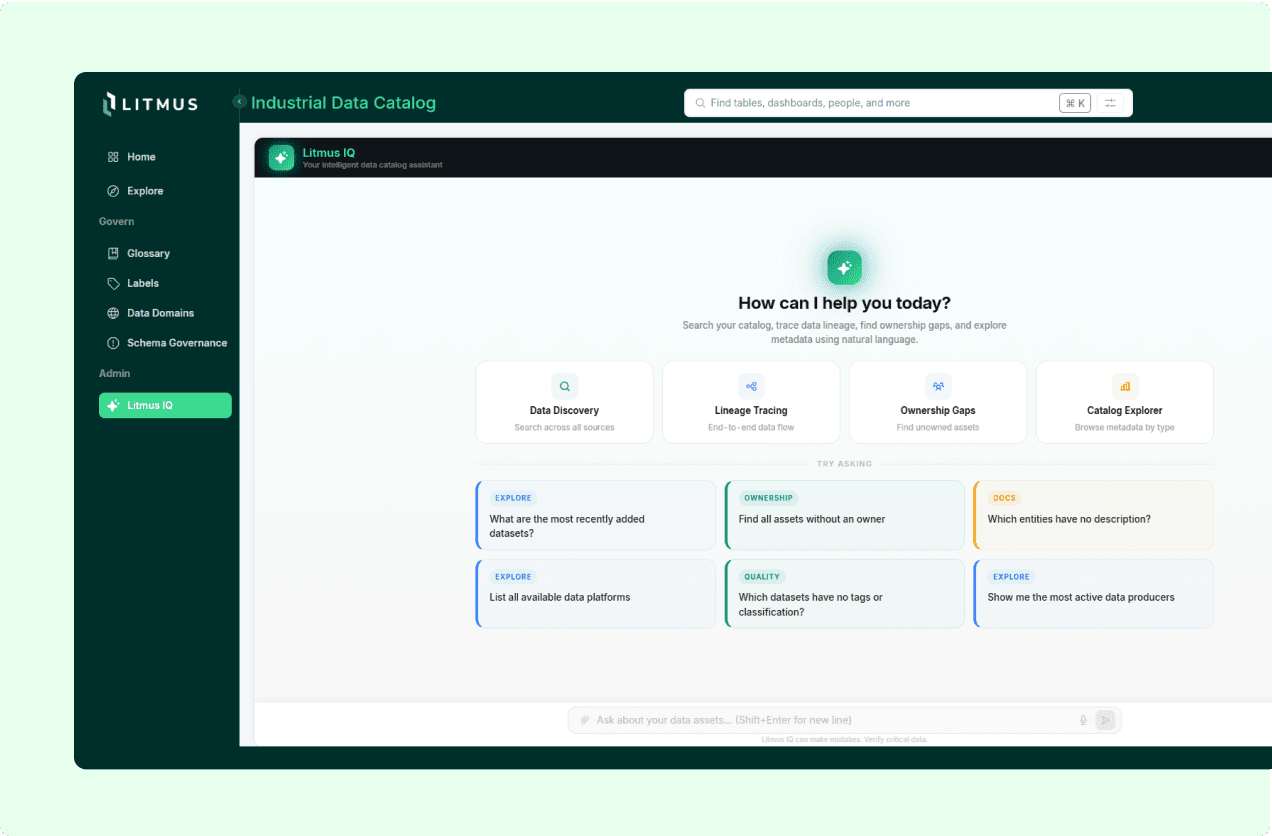
Industrial metadata becomes far more useful when people can ask questions of it in plain language. Litmus Data Catalog interprets, summarizes, and connects metadata across the environment—giving business users usable answers without SQL, tag lists, or system-specific expertise.
Key features:
Litmus Data Catalog creates a structured metadata operating model that improves trust, visibility, and consistency across industrial data systems.
Improve trust in analytics, KPIs, and AI outcomes


Expose lineage across systems and workflows

Enforce governance at the metadata level

Monitor drift and maintain metadata integrity

Add business and operational context with AI

Industrial teams use Litmus to standardize data architecture across plants and scale analytics and AI in production environments.
Case Study
A global brewing manufacturer deployed Litmus to replace legacy tools and standardize operational data across 95 sites. With a unified architecture built on Litmus Edge and cloud analytics, the organization streamlined data acquisition and established a consistent foundation for enterprise analytics.
Impact:
Quick answers to your industrial data questions.